
How to Build a Data Classification Scheme People Will Apply
A classification scheme works when someone who is not a specialist can label a dataset in a minute and then knows what to do with it. When a scheme fails that test, the cause is more likely to be its design than the people using it.
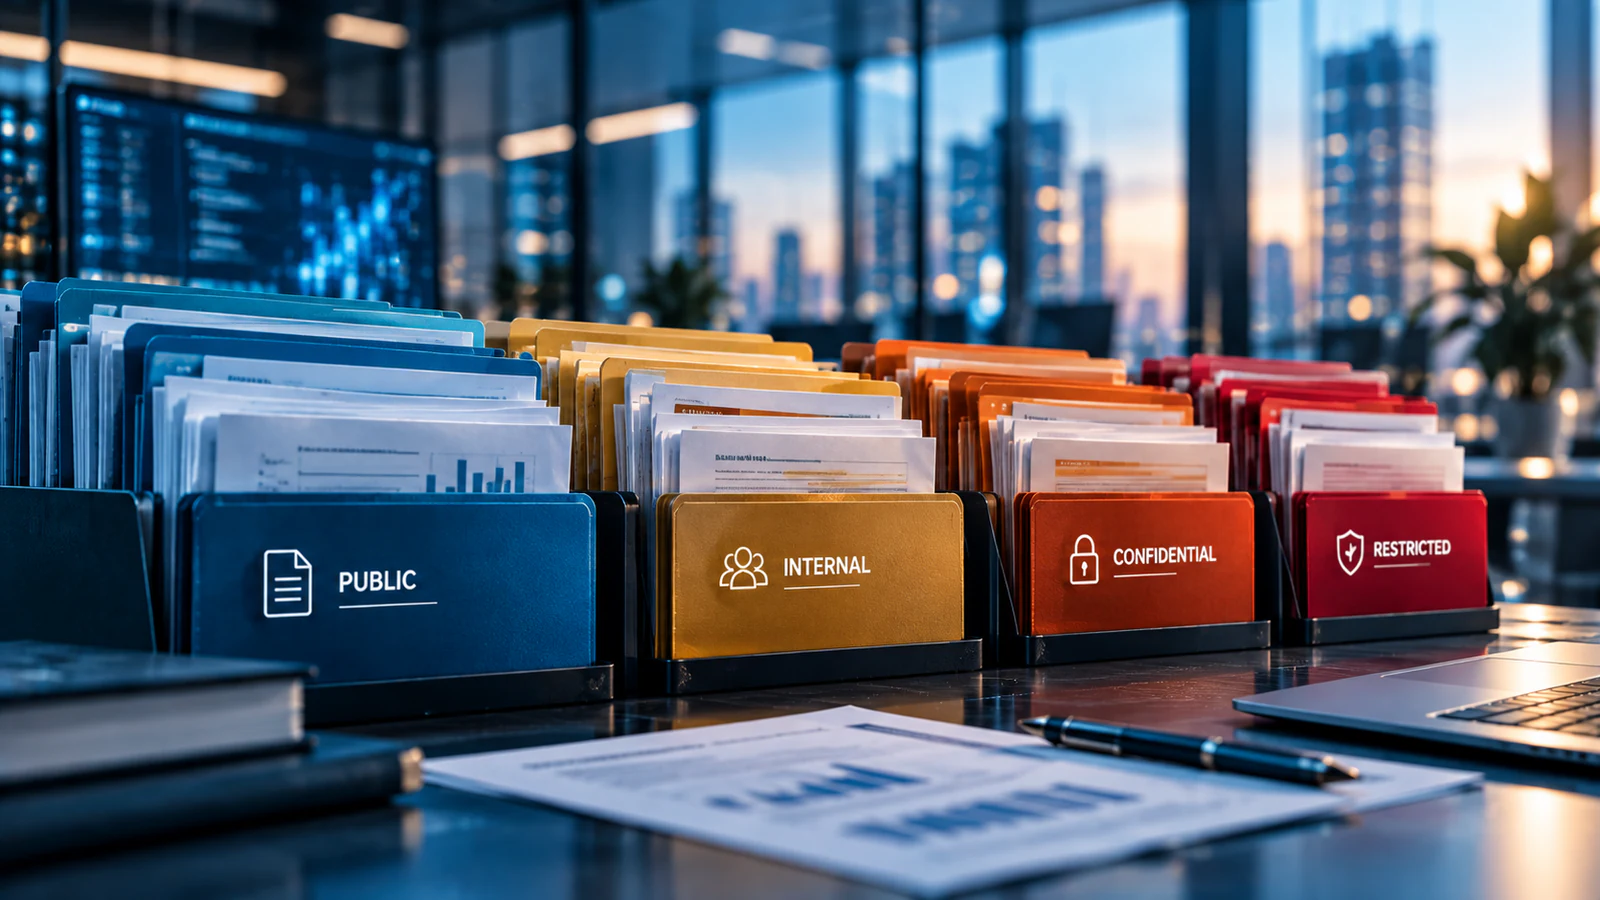
A data classification scheme sorts data into a small number of levels by how much harm would follow if it were exposed, altered or lost, and attaches handling rules to each level. Access controls, sharing decisions and retention all depend on it. If the labels are missing or wrong, none of those controls has anything reliable to act on.
A classification policy can exist for years alongside very little classified data. That is a design risk, and it follows from writing a policy to be complete and defensible: it ends up with more levels than anyone can distinguish, criteria that need an expert to interpret, and nothing that tells the person holding the data what to do differently at each level. The rational response is to label everything the same, or not to label at all.
The seven steps below build a scheme with the aim that it is applied. Classification is one policy area within a governance programme, which is described as a whole in what data governance is and what a working programme contains.
Step 1: Classify by consequence
The first decision is what the levels measure. The durable answer is consequence: what would happen to the organisation, or to individuals, if the data were compromised.
Two long-established government schemes take this approach. The US federal standard FIPS 199 defines three levels of potential impact, low, moderate and high, according to whether a loss could be expected to have a limited, a serious, or a severe or catastrophic adverse effect on operations, assets or individuals1. The UK Government Security Classifications Policy sets its tiers to be “proportionate to the potential impact of a compromise, accidental loss or incorrect disclosure” and to the level of interest expected from those who might seek the information2.
Classifying by consequence has a practical advantage over classifying by type of content. A list of content types, such as “contracts”, “HR records” or “customer data”, has no natural end, and every new kind of data needs a ruling. A consequence test can be applied to data nobody anticipated.
FIPS 199 also makes a point worth carrying into a business scheme. It assesses impact separately for three security objectives: confidentiality, integrity and availability1. A scheme that classifies only by confidentiality is making a reasonable start. It is still worth asking, for the data that runs the business, what the consequence would be if it were wrong or unavailable, because for some data that harm is greater than the harm of disclosure.
Step 2: Choose the number of levels, and keep it small
The governing principle is to use the smallest number of levels that results in meaningfully different handling.
With too few levels, unlike data is treated alike, so either sensitive data is under-protected or ordinary data is over-controlled. With too many, the risk is that people cannot tell adjacent levels apart and resolve the doubt by guessing, or by choosing the highest. A practical check is to ask whether two adjacent levels would be handled differently. If they would not, they are one level.
Both schemes above use three levels21. They show that a small set of tiers can operate in large, risk-sensitive institutions. They are two examples, and they do not establish what suits organisations in general, but they are a reason to question a design with six or seven.
When you find yourself wanting another level, consider a marking instead. The UK policy handles variation within its lowest tier this way: it keeps one tier and adds a “-SENSITIVE” marking and a short list of handling instructions for information that needs more care, stating that handling instructions “do not change the information’s classification”2. A marking such as “personal data” or “commercially sensitive” tells the handler something specific without multiplying the levels.
The table shows an illustrative four-level scheme. It is an example of the form and should not be read as a recommended standard.
An illustrative four-level classification scheme
| Level | Test: if this were disclosed without authority | Illustrative examples |
|---|---|---|
| Public | No harm. It is published or approved for publication. | Published reports, marketing material, public price lists |
| Internal | Minor harm or embarrassment. Not for release, but routine. | Internal procedures, team plans, most operational data |
| Confidential | Significant harm to the organisation or to individuals. | Personal data, contracts, unpublished financial results |
| Restricted | Severe or lasting harm. Access is by named individual. | Special category personal data, security credentials, legally privileged material |
Step 3: Write criteria a non-specialist can apply
The scheme is used by people for whom classification is a small part of the job. The criteria have to work for them.
Write each level as a question about consequence that can be answered without specialist knowledge, as in the table above. Follow it with a few examples drawn from your own organisation, because an example close to the reader’s own work is easier to apply than a definition. Then add two rules that remove much of the remaining doubt.
A default level. State which level applies when nobody has decided. In the illustrative scheme above we would make it the second level, Internal, which avoids treating unlabelled data as publishable without imposing controls that routine data does not need. Without a stated default, the status of unlabelled data depends on who is asked.
Rules for personal data. Data protection law already draws a distinction your scheme should respect. The UK Information Commissioner’s Office explains that the UK GDPR “singles out some types of personal data as likely to be more sensitive, and gives them extra protection”, and it lists those special categories, including data about health, racial or ethnic origin, and religious beliefs3. It also notes that other data, such as financial data, may be sensitive without being special category data3. A simple rule follows: personal data is never below a stated level, and special category data is never below the next one. That saves every individual from having to work it out.
Test the criteria before publishing them. Give ten real datasets to five people outside the governance team and see whether they reach the same answers. Where they differ, the criteria are at fault, and it is better to find that out before launch.
Step 4: Bind each level to handling rules
A label that changes nothing gives people no reason to apply it. Each level needs a short, specific set of rules that say what a person may and may not do.
The UK policy’s structure is a useful model. Each tier carries a baseline of security controls and behaviours, the baselines are cumulative so that each level builds on the one below, and an organisation may add controls above the baseline but not go below it2. Cumulative rules should be easier to learn, because each level is the previous one plus a few additions.
Four questions cover most of what a handler needs to know.
Illustrative handling rules by level
| Level | Who may access | Sharing outside the organisation | Storage | Disposal |
|---|---|---|---|---|
| Public | Anyone | Unrestricted | Any approved system | No special requirement |
| Internal | All staff | With a business reason | Approved systems only | Standard deletion |
| Confidential | Those with a role-based need | Under an agreement, approved by the data owner | Approved systems with access control and encryption | Secure deletion, recorded |
| Restricted | Named individuals approved by the data owner | By exception, approved by the data owner | Designated systems only, with access logged | Secure deletion, verified |
These rules are illustrative. Yours will depend on your systems and obligations. The Access Policy Checklist is a quick reference for the access controls a policy should cover.
Retention needs separate treatment, because it is easy to assume that classification settles it. Classification does not decide how long data is kept. Retention depends on the purpose for which the data is held. For personal data, the Information Commissioner’s Office puts the requirement plainly: “You must not keep personal data for longer than you need it”, and it expects a policy with standard retention periods and a periodic review of what is held4. What classification contributes is priority. The higher the level, the more it matters that a retention period exists and that disposal actually happens. The Data Retention & Lifecycle Schedule is a working template for recording periods and lifecycle handling by category of data.
Step 5: Decide who classifies
A scheme needs three answers about people.
Who decides the level. For significant data, the data owner decides, because the owner is accountable for who may access the data and for its protection. The UK government’s data ownership model makes owners accountable for limiting access to those authorised and for ensuring that a retention schedule is in place5. The roles and how to assign them are covered in data owners, stewards and custodians.
Who applies it. Whoever creates or receives the data applies the label, using the criteria. The UK classification policy is explicit that everyone who works with government information has a responsibility to safeguard it “irrespective of whether it is marked or not” and “must be provided with appropriate training”2. The second half of that matters as much as the first. A duty placed on people who have not been shown how to meet it is unlikely to be carried out.
Who implements it. The teams that run systems turn the handling rules into access controls, encryption and deletion routines. In the ownership model they implement the access policies specified by the owner5.
Write down the escalation route as well: whom to ask when the level is unclear, and who rules when two people disagree.
Step 6: Roll out by data domain
Classifying an entire estate at once carries an obvious risk: the inventory takes so long that it is out of date before it is finished.
Start with one or two data domains where the risk is highest or the need is most pressing, for example customer or employee data. Classify the datasets in that domain with their owner, apply the handling rules, and fix what the exercise exposes. Then move to the next domain, having learned what the criteria got wrong.
Three practical points apply as you go.
Classify structured data at the level of the dataset first, and go to individual fields only where it makes a difference. A table that contains one restricted column can be classified as restricted, or the column can be separated or masked so that the rest of the table is usable at a lower level. That is a design decision for the owner and the architect together.
Record the label where the data is described, so that it travels with the data. A classification held only in a policy document is invisible at the point of use. Recording it as metadata alongside ownership and definitions is one of the uses of a catalogue, which is discussed in data catalogue, business glossary or data dictionary. Labels also need to follow data as it moves between systems, which is why classification and mapping data flows are best done together.
Treat automated classification tools as an aid. They can find patterns that look like personal or financial data across a large estate, and that is useful for discovering what you hold. A tool cannot judge consequence, which is the test the scheme rests on, so someone still has to confirm the level. Where a data platform can enforce access by label, the label becomes far more valuable, and it becomes more important that it is right.
Step 7: Check that it is being applied
Without checking, there is no way to know whether a scheme is being applied. Four signals show whether it is working.
- Coverage. What proportion of datasets in the domains you have rolled out carry a label at all.
- Distribution. How labels are spread across levels. If almost everything is at one level, the scheme is not discriminating. Heavy use of the top level is the pattern to watch most closely. It has a cost, because over-classified data is harder to use and the controls lose credibility.
- Agreement. Sample labelled datasets and have someone else classify them independently. Disagreement points to unclear criteria.
- Consequence. Whether the handling rules are followed for a sample of higher-level data: who actually has access, and whether disposal has happened.
Set a review cycle for the scheme itself, and review it whenever your obligations change. We suggest a year as a starting interval; the right one depends on how quickly your data and obligations move. Reclassification should be normal. Data that was confidential before publication is public afterwards, and a scheme that cannot lower a level risks accumulating restrictions until people route around it.
What makes the difference
A scheme designed to be applied has a few properties. It has few levels. Its criteria are questions about consequence that a non-specialist can answer. Every level changes what a person does. Someone accountable decides the hard cases, and the scheme is introduced one domain at a time and checked. None of this requires software, although software helps once the scheme is sound.
The Data Classification Scheme Template sets out levels, criteria and handling rules in the form described here, ready to adapt.
Sources
- National Institute of Standards and Technology (US Department of Commerce). FIPS PUB 199, Standards for Security Categorization of Federal Information and Information Systems. February 2004.
- Cabinet Office (UK Government). Government Security Classifications Policy. Updated 5 August 2024.
- Information Commissioner’s Office (UK). What is special category data? (UK GDPR guidance).
- Information Commissioner’s Office (UK). Principle (e): Storage limitation (UK GDPR guidance).
- Government Digital Service (UK Government). Data ownership model (part of “Data ownership in government”). 16 April 2026.
This article is general professional information. It is not legal, regulatory or security advice. The government schemes cited are described as examples of design; they apply to the bodies they were written for. Obligations differ by jurisdiction and sector.